This tutorial has an example of something similar HOW TO: Program the native SpeechRecognizer for Continuous Dictation and to do things Giovana.
The relevant code would be something like this:
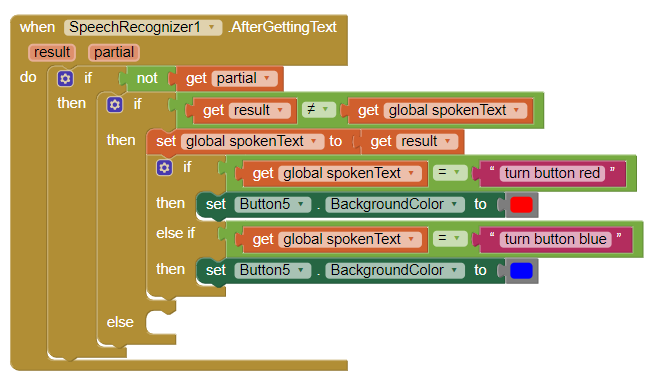
instead of saying Musicas ; your recognizer is returning musicas so you need to place
a 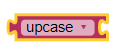 (or downcase) blocks on both sides of the comparison blocks ( to eliminate the difference between Musicas and musicas ) ... that is make them both MUSICAS so it will compare properly your spoken command.
Does that help?
Regards,
Steve