Follow-up: ChatGPT Modified My .aia Again — This Time to Add Drag-to-Reorder

This is a follow-up to my earlier post about ChatGPT being able to modify an existing MIT App Inventor .aia file and return a usable .aia that can be imported directly back into App Inventor.

In that earlier experiment, the interesting part was not simply that ChatGPT could suggest blocks. It actually modified the project file itself and returned a working .aia.

I tried it again.

This time the change came from a usability observation.

My card-game scoring app has a screen where the scorekeeper sets the player order before the game begins. The original version used a standard ListView along with buttons such as Move Up and Move Down.

When I showed the app to my wife, she did something completely natural: she pressed on a player’s name and tried to drag it up or down in the list.

That immediately made me wonder whether the screen should work that way instead.

Since a standard App Inventor ListView does not provide native drag-to-reorder behavior, I asked ChatGPT whether there was another way to accomplish it using App Inventor components.

The approach it came up with was to replace the reorder portion of the screen with a Canvas.

The basic idea is:

  1. Each player name is displayed in its own horizontal area on the Canvas.

  2. TouchDown determines which player the user touched.

  3. Dragged tracks the finger vertically.

  4. As the finger moves into another row, the underlying player list is reordered.

  5. The Canvas is redrawn to show the new order.

  6. The reordered list is then passed to the rest of the app just as it was before.

The part that continues the earlier experiment is how the change was implemented.

I uploaded my existing .aia file to ChatGPT and told it to modify only that screen while leaving the rest of the app alone.

ChatGPT then modified the .aia project files directly and returned a new .aia.

I imported that returned file into MIT App Inventor in the normal way.

No rebuilding the project from scratch.
No manually recreating all the blocks.
No copying code line by line.

The modified project simply came back as another App Inventor project file that I could import and test.

I am keeping my known-good version untouched and doing these experiments in a newer copy, so if something fails I can always go back.

What interests me most at this point is not just the drag-to-reorder technique itself. It is the broader possibility that an AI can make targeted changes to an existing App Inventor project, preserve the rest of the application, and return a usable .aia for continued development.

That is the part I wanted to follow up on from my previous post.

I would be interested to know whether others here have experimented with AI modifying .aia files directly, or whether anyone has tried a similar Canvas-based drag-to-reorder approach.

Hi @Dave_D,
honestly (as an old "machine code" programmer) I typically don't trust in AI generated code, but your experiment is very interesting and impressive. Your approach is different from the usual "dear AI, please do it on my behalf, because I'm lazy " :grin: (or not capable).
Another approach could be : instead of "using" (better, asking to) your wife to test your app, you could ask AI to generate test cases so to deeply test an app, instead of creating one (that will be very difficult to verify and validate due to poor specifications).
In a nutshell: instead of asking AI to generate (unreadable/untestable) code, one can ask AI to validate it. :thinking:
(Nice motorcycle, anyway)

Thanks, uskiara. I really appreciate that — especially coming from someone with your background. Your suggestion about using AI to generate test cases is very interesting too, and I can see real value in that approach.

I’ve been doing computer/programming “stuff” for many years, but this app itself was never meant to solve any world problems. I just wanted an easier way for my family to keep score when we play Oh Hell instead of using paper and pencil.

I may still try your AI-testing idea, although using my wife and sister-in-law as live test subjects during an actual card game is a lot more fun. :grinning_face_with_smiling_eyes:

And thanks about the motorcycle!

1 Like

I know of at least one member of our team who has done similar experiments. The CS Ph.D. in me cringes at the idea though because App Inventor has constraints that the LLM does not necessarily know about, so even though it may be able to produce an edit to the AIA file I assume it is not doing this directly, since an AIA file is actually a ZIP file.

Instead, what I deduce is happening is this is a combination of an internal harness implemented by OpenAI around their GPT models, i.e., the model makes a tool call to extract the appropriate files from the AIA file, manipulates those files, and then updates the contents of the AIA. Each screen in App Inventor is composed of two files, a scm file that contains a JSON representation of the design, and a bky file that contains an XML representation of the blocks. These representations are much easier to manipulate than the compressed representation encoded in the AIA.

Of course, this has some consequences. First, the full AIA has to still be sent, which may cost tokens, and depending on the operation requested the LLM may issue a tool call that uses more tokens than is strictly necessary. As a concrete example, reordering the components on the screen strictly requires the .scm file but for validity an LLM may want to consider both the .scm and .bky files since it may be unaware of the relationships between the two.

In general, I would say this is fine--if the model can always generate a valid scm/bky file. The tradeoff, of course, is that tokens = $$$ and the more tokens one uses the more money one spends. Our work on Aptly looked to address this challenge by creating a language that is semantically equivalent to App Inventor while looking like Python, thus providing a compact representation of App Inventor projects while trying to minimize the token cost.

Personally, I believe there's a difference between "next likely token" and "next valid token" and this gets particularly tricky when the tokens are actually cordinated between two different files, i.e., a token in the bky file may only be valid if there is a corresponding token in the scm file. This is further complicated by the fact that we release new versions of App Inventor such that if the cutoff for training was 6 months ago and we've released a new component since then, a token that is technically valid today wouldn't be in training data from 6 months ago. Less likely, we rarely rename methods/properties so what was a valid token for many years may no longer be valid. This is fine so long as the files contain the corresponding version number--our upgraders will take care of renaming things as the version numbers change... but if the LLM produces version X and token Y where token Y was renamed to Z in version W < X, then you have a problem and App Inventor will likely throw its hands up when it finds the now invalid name.

All that said, App Inventor apps follow a well defined grammar. Aptly is a formalization of that grammar in a Python-like script, and the scm/bky files are a realization of apps within that grammar. Teh grammar is implicitly defined by the App Inventor platform itself (honestly, I'd love to see this get formalized a la Aptly and then worked backward to what the platform now does). But... LLMs are not necessarily following a formal grammar, which may lead to problems. App Inventor will not gracefully handle deviations from the grammar since it assumes that App Inventor projects are generated by App Inventor so a violation of its semantics effectively would be a bug. When we add/update/remove semantics, we work very hard in each version to ensure that all App Inventor projects from the beginning will be updated to a valid representation in the new version and do something reasonable as far as the user is concerned (ideally perfect, but that's not always possible due to things like changes in the platforms themselves that cause us to reduce the behavior of blocks).

That's a fairly long-winded description of what's possibly going on and how there are formal ways we can think about the LLM interactions with App Inventor projects. At the end of the day, I think we all want software that is predictable, and at least as far as LLMs are concerned, their nondeterministic nature definitely makes predictable more difficult.

1 Like

In effect the "fantasy" of users is much wider than the experience and the capability of testing engineers (in inventing test cases). Therefore wives or kids are the best for "unexpected behavior" finding. :nerd_face:
Best wishes for your project.

PS though I'm 68 I still rde my off-road bike, the only "problem" is that instead of being a two stroke (very noisy and smoky) is an electric one.... :joy:

I’d say very interesting, could you share the model and the prompts you used to achieve this?

Thanks @ewpatton for your very detailed explanation !
In our (software guys) jargon we used to say "the bug is always lurking" ... for this reason I've said that probably instead of letting AI to generate the (unpredictable) code, it's better to ask Ai to generate test cases. :thinking:

Thanks, guys. I think all three of you are looking at this from a much more sophisticated software-engineering angle than I was. :grinning_face_with_smiling_eyes:

I’m a pretty simple guy trying to create a workable, simple app to keep track of a rather convoluted score for a simple card game.

My question really was only this:

Can I hand ChatGPT my existing, real .aia file, describe a change, get back another .aia, import it into the version of MIT App Inventor I’m using right now, and have it work?

Did it work correctly the first time? Nope.
Did it work correctly every time? Nope.
Did it eventually work? Yep.

A little history may explain how I got here.

My family and I like to play Oh Hell. Creating the paper score sheet and then actually keeping track of the score gets burdensome. I first used Excel to create both a printable score sheet — useful while we’re off in the Canadian hinterlands fishing for walleye — and a macro-driven version that worked quite well on my HP laptop. Unfortunately, it didn’t work nearly as well when we played at my sister-in-law’s house.

So I started talking with ChatGPT about converting the Excel version into something I could use on Android. We couldn’t readily find a good path. Since I was raised in the BASIC family back in the dark ages, I next went looking for some kind of Visual Basic-to-Android converter. No luck there either. I’m not saying such things don’t exist; I just didn’t find one that solved my problem.

So I turned my AI attention to finding a relatively simple app-building system, and that led me to MIT App Inventor.

After a week or so, I had my handy-dandy little card-scoring app.

The workflow eventually became pretty straightforward:

Create an MIT App Inventor project, sometimes with a couple of relatively blank screens. Tell ChatGPT what I want a particular screen to do. Export the project. Put the .aia into a ChatGPT conversation — sometimes a normal chat worked and sometimes I used Work. Tell ChatterGPT to do its magic. Get the modified .aia back onto my laptop. Import it into MIT App Inventor. Test it.

Rinse and repeat.

One instruction has served me especially well after several years of heated discussions with ChatGPT:

“Look at what I actually have. Use MIT App Inventor. Use the blocks and components available to me. Don’t invent something because another programming environment can do it.”

From my simple-guy perspective, I had a need and I found a solution to that need.

Will this solve world hunger? Nope.
Will it bring peace to distant shores? Nope.
Will it reverse climate change? Nope.

Did it cost me anything extra? Nope.

Will it make it a little easier for me to keep score after a tasty fish fry at a remote Canadian fishing camp? Yep. :grinning_face_with_smiling_eyes:

Can we guarantee that an LLM will always generate a formally valid App Inventor project? Obviously not.

Can I use this thing to keep score when my wife, sister-in-law and the rest of the family play Oh Hell?

Yep.

And finally, cheers to anybody — male or female — who is still able to enjoy two wheels at 60, 68, 74 or beyond, regardless of what kind of motor is turning them. :motorcycle::grinning_face_with_smiling_eyes:

I’m concerned with the notion of having an LLM, or anyone or anything alter a project (via the .aia file) directly. App Inventor is fragile in the sense that it expects that the content of an .aia file was created by App Inventor and not altered outside of it. As a result, it trusts the content. If the content is incorrect in some way, it will likely lead to an “An Internal Error Has Occurred.” The project may then become untenable, as in you cannot load it into App Inventor and you might not even be able to delete it!

We are experimenting with AI tools that work within App Inventor, but we don’t have anything we can publicly demonstrate yet.

I also am concerned with the case where someone alters an .aia file, which causes some error, which is then reported here on the community forum without necessarily mentioning that the .aia file was modified. I have lost several hours of time on cases looking for nonexistent bugs based on a modified .aia file causing some error.

I’m looking into how to digitally sign a .aia file so at least we, the community, can detect that a .aia file was modified outside of the App Inventor context.1

Footnotes

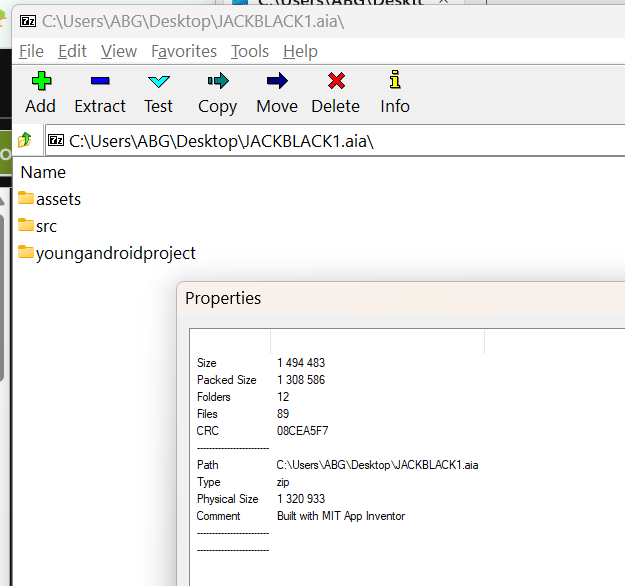
1 Actually, .aia files have the ZIP comment field set to “Built with MIT App Inventor.” If you find a .aia file without this comment, it means it was put together by the normal “zip” utility and not MIT App Inventor.

How to see that comment in 7zip, under the Info pulldown:

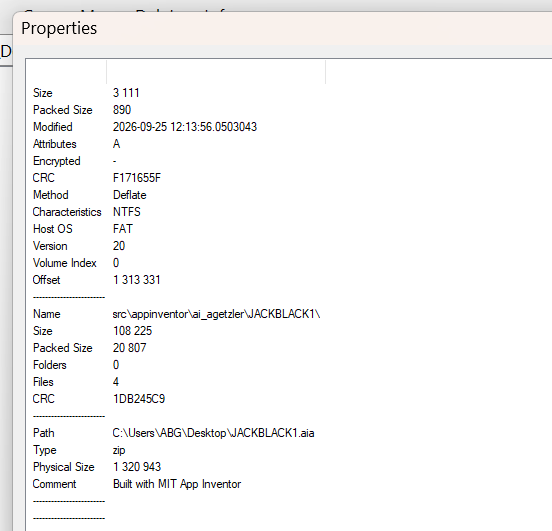
I have not yet tried to see if it remains unchanged after editting subfiles in 7zip.

P.S. 7zip does not change the comment during surgery:

Maybe add the CRC to the comment to preserve provenance?

I understand the concern, especially if somebody modifies an .aia, breaks it, and then comes here crying that App Inventor has failed them without mentioning the outside modification.

In my case, though, I didn’t arrive at App Inventor because I was looking for a way to experiment with AI editing .aia files. I arrived here because I wanted a simple Android app that would keep score for one particular card game.

Once I had most of the app working, there were parts of the build that I understood perfectly well but simply didn’t feel like spending the time constructing block by block.

I wasn’t asking AI to rescue me from something I couldn’t do; I was delegating grunt work.

My attitude was basically: “I know what I want this screen to do. I don’t want to spend an afternoon assembling all of it. Here’s the project — you take over this laborious part.”

So the .aia modification wasn’t really the objective. It was just the shortcut that happened to work.

I keep a known-good version, make a copy, let ChatGPT work on the copy, import it, and test it. If it breaks, I throw that version away and go back to the one that works.

I’m not trying to change the future of software development here. :grinning_face_with_smiling_eyes: I’m trying to avoid paper and pencil while keeping score in a family card game.

So yes, I understand the concern about externally modified projects and support issues. But in my little corner of the world, this is mostly about saving myself some tedious work.

No world domination planned. Maybe a chocolate milkshake and a Hallmark movie afterward. :grinning_face_with_smiling_eyes:

I’m with you. I also use various LLMs to deal with “grunt work.”

The challenge, from an educational perspective, that we face is where to draw the line on LLM use. It is one thing for an LLM to help a student learn how to code. It is a different thing to have the student ask the LLM to do their homework!

In MIT App Inventor, we really have at least two audiences.

  1. People just want to write an app that does something for them.
  2. Students whom we wish to use App Inventor to learn how to code. To remove the “magic” behind technology.

The approach to using an LLM for these two constituencies is likely different. We’ll need to figure out how to address both!

-Jeff

Jeff, your distinction between those two audiences got me thinking in a slightly different direction.

Way, way, way back in the day, I went back to school as an adult — husband, father of three, and at various times employed, laid off, employed, laid off. I needed the degree because I needed the job.

At that stage of my life I had finally become an A student. (A very late apology to all of my high school teachers. :grinning_face_with_smiling_eyes:)

In one class I turned in what I thought was a pretty good original writing assignment and got a C. I asked the professor why. His answer was basically that I had not quoted enough established authors.

I told him it was supposed to be an original piece of work, not a regurgitation of somebody else’s ideas. He didn’t care. More research. More citations. More established authors.

Alrighty then.

I subscribed to eLibrary — which tells you how long ago this was — and from then on I became very good at producing the kind of researched, properly quoted work the system wanted. My A average returned.

So I wonder whether the educational question today should be a little broader than “How do we keep students from having AI do their homework?”

Maybe we should be teaching them how to use whatever technology is available to them while also teaching them how to research properly, how to decide whether a source is trustworthy, how to find holes in an argument, how to verify what an AI tells them, and most importantly, how to use all of that to create something that is actually their own.

My wife once told me I should write a book. So I did. I used AI for some of the labor — spelling, grammar, polishing, and helping me check historical details across different time periods. But the story, the decisions, the characters, and the final judgment were mine.

Later I used AI heavily while creating a series of preschool children’s books based on my special-needs grandson. Those books have very few words and lots of pictures, and I’m certainly not an illustrator. AI made it possible for me to create something I probably could not have produced otherwise.

To me, that is the interesting part of this whole discussion.

The goal should not simply be to keep students inside the old box but to get them to think outside of any box (by the way, that’s the subject of one of the other books that I may or may not write There’s Always Another Box … and no, I’m not thinking that will be a best seller either lol)

It should be to teach them how to use the new tools without surrendering judgment, curiosity, research skills, or creativity.

1 Like